what i'm into
- Claude Code, Codex, Hermes, whatever's smartest that day
- agent workflows and a second brain that actually remembers things
- open models on my own rig when they earn it
- posting the full config, flags included
cenote
DeepSeek-V4.1-Flash on one RTX 3090, native on windows
my windows port of Xolotl's DeepSeek engine. the experts live across vram, ram and the nvme, so a model way bigger than the card still runs at home.
- code
- 18.6 tok/s
- prose
- 12.3 tok/s
- prefill, 13k prompt
- 131.9 tok/s
- vram + ram
- 24 + 128 GB
DeepSeek-V4.1-Flash-1017, lxe's dsx 2-bit build (148 GB) plus DeepSeek's 203 GB engram tables. greedy, 400 tokens, median of 3, with the september draft model (code is 14.0 tok/s without it). prefill is 13,341 tokens in 101 s. measured 2026-10-18.
credit where it's due engine: Xolotl by Indras-Mirror, built on Strata by Niko1221 and ggml/llama.cpp. model: DeepSeek. quant: lxe. mine: the windows port, a windows-only crash fix, and the tuning.
the rig
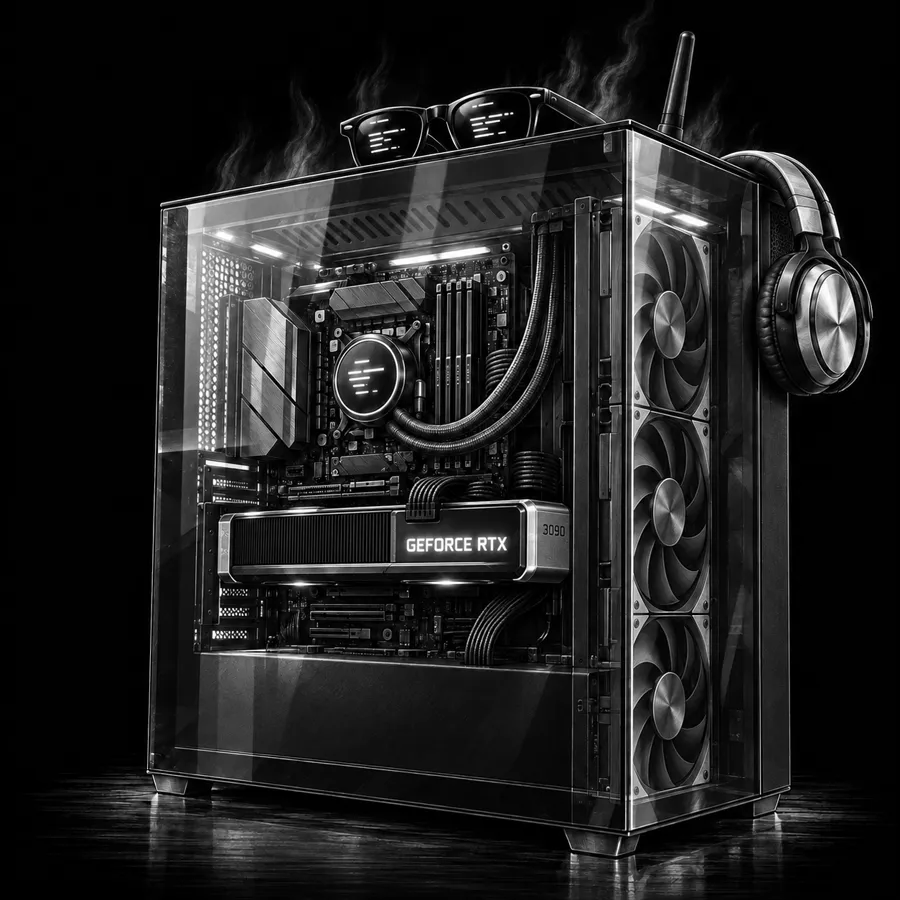
- gpuRTX 3090 Founders Edition, 24 GB
- ram128 GB DDR4-3200
- cpuRyzen 7 5800X
- ssdSamsung 990 EVO Plus NVMe
- oswindows 11
plenty of rigs beat this one. i just like seeing how far one 3090 goes.